Enterprise RAG Knowledge Assistant
A Python-based enterprise knowledge assistant that uses semantic retrieval, FAISS and Azure OpenAI to generate grounded answers with visible document sources.
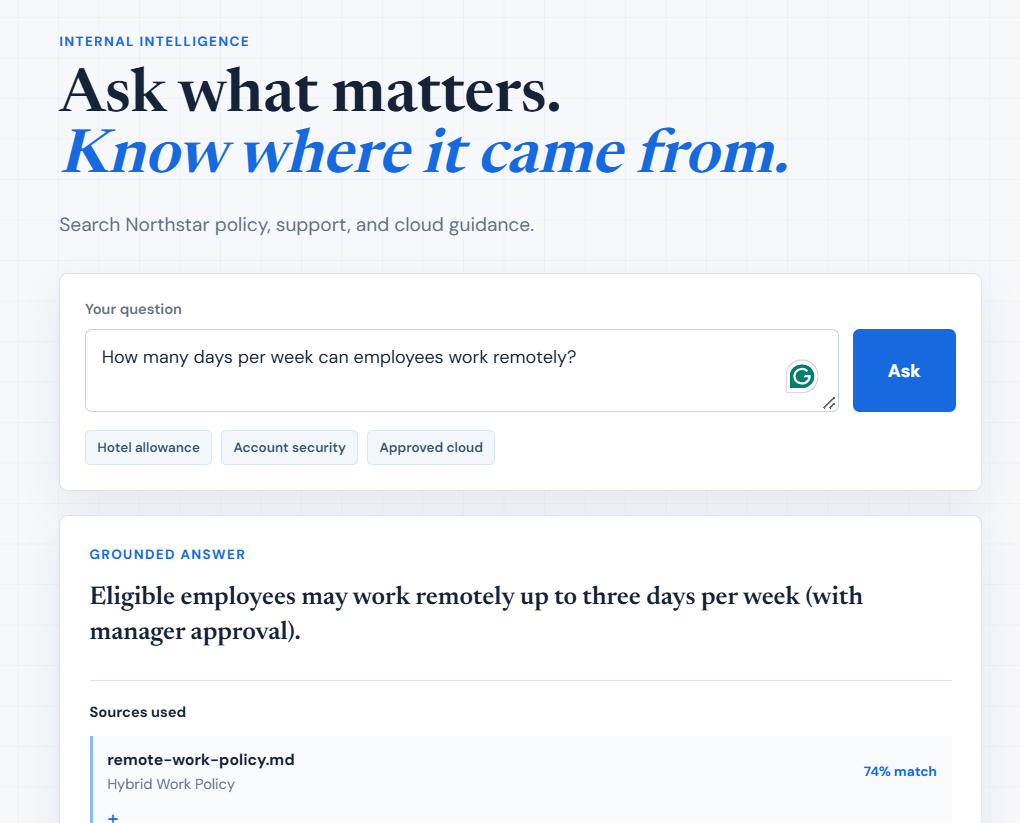
Overview
The Enterprise RAG Knowledge Assistant is a working Retrieval-Augmented Generation application built to demonstrate how generative AI can answer questions using trusted enterprise knowledge rather than relying only on a language model's pretrained knowledge.
The application uses a fictional organization and a collection of internal business documents covering topics such as employee policies, information security, expenses, IT support, remote work and cloud-platform guidance.
When a user asks a question, the application performs semantic retrieval across those documents, identifies the most relevant pieces of information and provides that context to Azure OpenAI before generating an answer.
The response includes the underlying document sources so the user can see where the information came from.
The project was deliberately designed as a small, transparent RAG implementation rather than a large enterprise platform.
The Challenge
Enterprise knowledge is often distributed across documents, policies, technical guides and organizational systems.
A general-purpose language model may be able to answer broad questions, but it does not automatically know an organization's current policies or internal documentation.
For example, consider questions such as:
How many days per week can employees work remotely?

What is the maximum hotel allowance for business travel?

What should I do if I suspect my account has been compromised?

Which cloud services are approved for confidential workloads?
These questions require organization-specific information.
Allowing a language model to answer them using only pretrained knowledge creates a significant risk of plausible but unsupported responses.
The objective of this project was therefore to build a system that follows a different process:
Retrieve first.
Generate second.
Show the sources.
Why RAG?
Retrieval-Augmented Generation combines information retrieval with language-model generation.
Instead of sending only the user's question to a language model, the application first searches a trusted knowledge base.
The most relevant information is then supplied as context for answer generation.
Conceptually:
User Question
      |
      v
Semantic Retrieval
      |
      v
Relevant Enterprise Knowledge
      |
      v
Azure OpenAI
      |
      v
Grounded Answer
      |
      v
Sources
This provides an important distinction between a generic chatbot and an enterprise knowledge assistant.
The model is not expected to know the fictional organization's policies independently.
The application retrieves those policies when they are needed.
Architecture
The application uses a deliberately lightweight Python-first architecture.
Enterprise Documents
        |
        v
Document Ingestion
        |
        v
Text Chunking
        |
        v
Azure OpenAI Embeddings
        |
        v
FAISS Vector Index
        |
        |
        |  Runtime
        v
User Question
        |
        v
Question Embedding
        |
        v
FAISS Similarity Search
        |
        v
Top Relevant Chunks
        |
        v
Grounded Prompt
        |
        v
Azure OpenAI
        |
        v
Answer + Sources
        |
        v
FastAPI
        |
        v
Web Interface
The architecture separates the RAG workflow into understandable stages without introducing unnecessary infrastructure.
Enterprise Knowledge Base
The demonstration uses fictional enterprise documents stored directly with the project.
The knowledge base includes documents such as:
employee-handbook.md
remote-work-policy.md
information-security-policy.md
expense-policy.md
it-support-guide.md
cloud-platform-guide.md
Each document represents a different area of internal organizational knowledge.
The content is fictional and created specifically for the portfolio demonstration.
No real company or employee information is used.
Document Ingestion
Before questions can be answered, the enterprise documents pass through an ingestion pipeline.
The ingestion process:
- Reads documents from the knowledge directory
- Extracts the document text
- Splits the text into smaller chunks
- Preserves document metadata
- Generates vector embeddings
- Stores the vectors in a FAISS index
- Stores chunk metadata for later source attribution
The ingestion workflow is intentionally explicit so the core RAG process remains easy to understand.
Instead of hiding retrieval behind a large framework, the project uses straightforward Python code to demonstrate what happens at each stage.
Chunking
Large documents are divided into smaller pieces before embedding.
Chunking allows retrieval to identify the specific parts of a document that are relevant to a question instead of returning an entire file.
Each chunk retains information about its source document.
Conceptually:
remote-work-policy.md
        |
        v
  Document Text
        |
        v
+------------------+
| Chunk 1          |
+------------------+
| Chunk 2          |
+------------------+
| Chunk 3          |
+------------------+
        |
        v
     Embeddings
This metadata later allows the frontend to show which document supported the generated answer.
Embeddings
Both enterprise document chunks and user questions are represented as vector embeddings.
An embedding captures semantic meaning as a numerical representation.
Questions with similar meaning can therefore retrieve relevant information even when the wording is different.
For example:
How often may staff work from home?
can retrieve content discussing:
Employees may work remotely...
even though the exact wording is different.
This semantic matching capability is what makes vector retrieval useful for natural-language enterprise search.
FAISS Vector Retrieval
The application uses FAISS as its local vector-search engine.
During ingestion, document vectors are added to the FAISS index.
At runtime:
- The user's question is embedded.
- FAISS compares the question vector with document vectors.
- The most similar chunks are retrieved.
- Retrieved text and metadata are returned to the RAG pipeline.
This keeps the demonstration small and self-contained.
There is no separate vector-database server to manage.
For this portfolio use case, that simplicity is intentional.
Grounded Generation
Retrieval alone does not produce the final customer-facing answer.
After the relevant document chunks are selected, the application constructs context for Azure OpenAI.
The model receives:
System instructions
        +
Retrieved enterprise context
        +
User question
The instructions tell the model to answer using the supplied enterprise knowledge.
If the retrieved context does not contain enough information, the assistant should communicate that limitation rather than inventing a fictional company policy.
This is an important design principle of the project:
An enterprise AI assistant should be able to say that the available knowledge is insufficient.
Source Citations
A key requirement for the project was making retrieval visible to the user.
Generated answers therefore expose their supporting document sources.
For example:
Answer

Employees may work remotely according to the
conditions defined in the hybrid work policy.

Sources

remote-work-policy.md
This improves transparency and makes the application easier to evaluate.
It also demonstrates that the answer is connected to retrieved enterprise knowledge rather than produced by an ungrounded language model call.
Retrieval Transparency
The application was designed so retrieval does not have to remain hidden behind the final answer.
The user interface can expose information about the retrieved context, including the documents selected by semantic search.
This is particularly useful in a RAG demonstration because it makes the architecture visible:
Question
   |
   v
Retrieved Documents
   |
   v
Relevant Context
   |
   v
Generated Answer
A portfolio visitor can therefore see that the application performs actual retrieval before generation.
Example Questions
The knowledge assistant can be tested with questions such as:
How many days per week can employees work remotely?
What is the maximum hotel allowance for business travel?
What should I do if I suspect my account has been compromised?
What is the escalation process for a critical IT incident?
Which cloud services are approved for confidential workloads?
Different questions should retrieve information from different enterprise documents.
This demonstrates semantic search across multiple knowledge domains.
Handling Unknown Information
One of the most important RAG behaviors is what happens when the answer does not exist in the knowledge base.
Suppose a user asks:
What is the company's parental leave policy?
If the available documents do not contain a parental leave policy, the assistant should not create one.
Instead, the application is designed to communicate that the available knowledge does not contain enough information.
This behavior is important because a convincing but fabricated enterprise policy would be significantly worse than an honest limitation.
Application Layer
FastAPI provides the Python application and API layer.
The application is responsible for:
- Receiving the user's question
- Validating input
- Running semantic retrieval
- Building grounded context
- Calling Azure OpenAI
- Returning the generated answer
- Returning source metadata
- Handling application errors
The browser never communicates directly with Azure OpenAI.
Instead:
Browser
   |
   v
FastAPI
   |
   +----------------------+
   |                      |
   v                      v
FAISS Retrieval      Azure OpenAI
   |                      |
   +----------+-----------+
              |
              v
       Answer + Sources
This keeps Azure credentials on the server side.
User Interface
Although Python is the primary language of the project, the application includes a polished web interface designed specifically for the portfolio demonstration.
The interface focuses on the RAG experience rather than behaving like a generic AI playground.
The design includes:
- Enterprise knowledge-assistant branding
- Natural-language question input
- Suggested questions
- Generated answers
- Visible source documents
- Retrieved-context information
- Loading states
- Error handling
- Responsive layout
- Professional blue and indigo visual styling
The goal was:
Simple internally
        +
Professional externally
Azure OpenAI Integration
Azure OpenAI is used for the AI components of the application.
Environment-specific configuration is kept outside the source code.
The Python backend reads configuration using environment variables rather than exposing credentials to the browser.
The architecture follows:
Browser
   |
   | No Azure credentials
   v
FastAPI
   |
   | Server-side credentials
   v
Azure OpenAI
This same separation is maintained in the deployed version.
Deployment
The complete application is deployed to Vercel.
The deployment includes:
- Python FastAPI backend
- Static frontend assets
- Prebuilt FAISS retrieval index
- Enterprise document metadata
- Secure environment variables
- Azure OpenAI connectivity
The prepared retrieval index is deployed with the application and loaded for read-only semantic search.
This keeps the live portfolio demonstration self-contained without introducing a separate hosted vector database.
Why I Kept the Architecture Simple
A production enterprise RAG platform could introduce many additional technologies:
- Managed vector databases
- Azure AI Search
- Authentication
- Access-control filtering
- Document connectors
- Databases
- Redis
- Message queues
- Background ingestion workers
- Kubernetes
- Observability platforms
- Complex orchestration frameworks
Those technologies can be appropriate in larger systems.
They were deliberately excluded from this implementation.
The purpose of this project is to demonstrate the core RAG workflow clearly.
The resulting architecture remains easy to follow:
Documents
   |
   v
Chunks
   |
   v
Embeddings
   |
   v
FAISS
   |
   v
Retrieval
   |
   v
Context
   |
   v
Azure OpenAI
   |
   v
Grounded Answer
Every major part of the application has a clear purpose.
Why I Avoided a Large RAG Framework
The central RAG implementation uses straightforward Python rather than hiding the complete workflow behind a large orchestration framework.
This was a deliberate learning and design decision.
It makes it easier to understand:
- Where documents are loaded
- How text is chunked
- Where embeddings are generated
- How vectors are stored
- How similarity search works
- Which chunks are retrieved
- How context reaches the language model
- How sources are returned to the frontend
For this project, transparency was more valuable than abstraction.
Security and Privacy
The project follows several simple security principles:
- Azure credentials remain server-side
- Secrets are excluded from Git
- Browser JavaScript does not receive Azure credentials
- Only fictional enterprise documents are included
- No real employee information is stored
- No real organizational policies are used
- The assistant does not claim access to systems that are not connected
The public repository therefore contains application code and fictional demonstration data without exposing private enterprise information.
What This Project Demonstrates
The Enterprise RAG Knowledge Assistant demonstrates practical experience with:
- Python application development
- FastAPI
- Retrieval-Augmented Generation
- Document ingestion
- Text chunking
- Embeddings
- Vector search
- FAISS
- Semantic retrieval
- Azure OpenAI
- Grounded generation
- Source attribution
- Environment-variable management
- Server-side AI integration
- Deployment of a Python AI application
- AI hallucination control through retrieval
More importantly, the project demonstrates the complete flow from enterprise document to grounded AI answer.
What I Learned
Retrieval is as important as generation
A strong language model cannot reliably answer organization-specific questions if the correct information never reaches the model.
Retrieval quality is therefore a central part of RAG quality.
Sources make RAG easier to trust
Showing the retrieved documents gives users and developers a way to inspect where an answer came from.
This makes the system easier to evaluate and debug.
Unknown information should remain unknown
A production-minded knowledge assistant should not turn missing documentation into invented organizational policy.
Simple implementations improve understanding
Building the retrieval pipeline directly in Python made every stage of the RAG process visible.
This provides a stronger understanding of the architecture than simply calling a high-level framework.
Deployment constraints influence architecture
The application was designed so the retrieval index could be packaged with the deployment and loaded read-only in the production environment.
This allowed the live demo to remain simple without introducing another hosted datastore.
Future Improvements
A larger production version could extend this architecture with:
- Azure AI Search or another managed vector database
- Hybrid keyword and vector search
- Reranking
- Document-level access control
- Enterprise authentication
- SharePoint or document-management connectors
- Automated ingestion pipelines
- Persistent conversation history
- User feedback
- Retrieval evaluation
- Groundedness evaluation
- Monitoring and tracing
- Human escalation
- Larger document collections
These capabilities are deliberately outside the scope of the current portfolio implementation.
Outcome
The finished project demonstrates a complete RAG workflow using a small and understandable architecture.
Enterprise documents are transformed into searchable vectors, user questions trigger semantic retrieval, relevant context is supplied to Azure OpenAI and the resulting answers expose their supporting sources.
The final result is a working Python-based enterprise knowledge assistant rather than a conceptual architecture diagram.
Live demo: Open Enterprise RAG Knowledge Assistant
Source code: View source code on GitHub
More Projects
Explore more AI projects, architectures and practical implementations.
AI Agent Framework
An architecture for building intelligent agents that can reason over tasks, use tools, collaborate and execute multi-step enterprise workflows.
Customer AI Assistant
NovaCare is an AI-powered customer support assistant built with Next.js and Azure OpenAI, combining conversational memory, company-specific knowledge and safeguards against fabricated customer information.